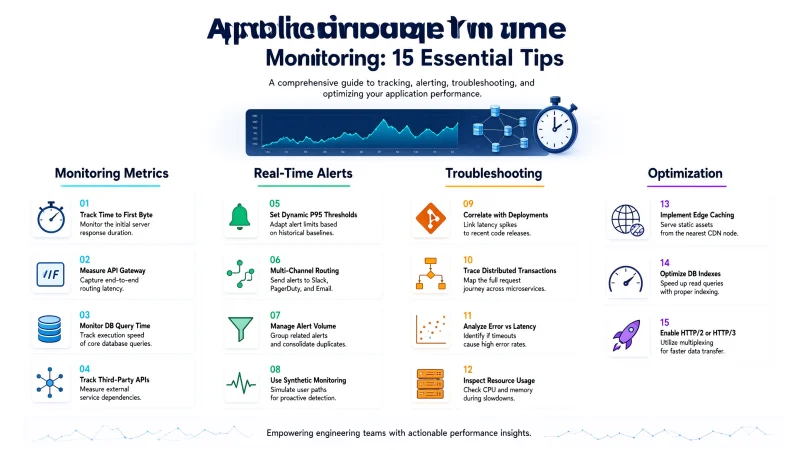
Application response time monitoring helps you track how quickly an application responds to user requests, identify performance issues, and deliver a smoother user experience. Whether you’re monitoring a website, business app, or API, the right approach helps you spot slowdowns before users start complaining.
Top alternatives: Application performance monitoring, response time tracking, website speed monitoring, API latency monitoring, real-time application monitoring.
Ever clicked a website, waited a few seconds, and immediately wondered whether your internet was broken or the application had officially taken the day off? We’ve all been there. In a world where users expect instant results, even a small delay can turn a great digital experience into a frustrating one.
That’s where application response time monitoring comes in. It helps developers, IT teams, business owners, and system administrators understand how quickly applications respond to user requests. From tracking website loading speeds to investigating slow APIs and unexpected server delays, monitoring makes it easier to identify performance problems before they affect customers.
Whether you’re managing an online store, maintaining a business platform, or optimizing a mobile application, understanding response times matters. The right monitoring strategy can improve reliability, reduce frustration, and keep users coming back. Think of it as giving your application a regular performance checkup, minus the waiting room.
1. Essential Application Response Time Monitoring Tips
1. Track Every Important Request
Example: When monitoring a shopping website’s checkout process.
Meaning: Measures how quickly critical application requests complete.
2. Set Clear Response Time Targets
Example: When establishing performance expectations for a customer portal.
Meaning: Defines acceptable response times for essential user actions.
3. Monitor Real User Experiences
Example: When checking whether customers experience slow page loads.
Meaning: Reveals performance from the user’s actual perspective.
4. Measure Response Times Continuously
Example: When watching an application during business hours.
Meaning: Helps identify slowdowns as they develop.
5. Track Average Response Time
Example: When comparing application performance across different days.
Meaning: Provides a basic overview of typical responsiveness.
6. Check the Slowest Requests
Example: When investigating a report that certain pages take forever.
Meaning: Highlights requests that may require optimization.
7. Monitor Critical Transactions
Example: When tracking login, payment, and account creation workflows.
Meaning: Prioritizes actions that directly affect users.
8. Compare Peak and Off-Peak Performance
Example: When an online store slows down during evening sales.
Meaning: Shows how traffic patterns influence response times.
9. Record Historical Performance
Example: When comparing this month’s response times with last month’s.
Meaning: Helps reveal recurring issues and long-term trends.
10. Watch for Sudden Response Time Spikes
Example: When a business application suddenly becomes sluggish.
Meaning: Helps identify unusual performance changes.
11. Measure Server Processing Time
Example: When checking how long backend operations take.
Meaning: Helps isolate delays caused by server-side processing.
12. Review Monitoring Results Regularly
Example: When preparing a weekly application health report.
Meaning: Turns performance measurements into actionable improvements.
2. Real-Time Application Monitoring Strategies
1. Watch Performance as It Happens
Example: During a product launch that attracts thousands of visitors.
Meaning: Helps teams react quickly to developing performance problems.
2. Create Live Performance Dashboards
Example: When displaying response times for several production services.
Meaning: Makes important performance indicators easier to understand.
3. Monitor Traffic Surges
Example: When a promotional campaign suddenly increases website visits.
Meaning: Reveals whether an application can handle changing demand.
4. Set Automatic Performance Alerts
Example: When a checkout service exceeds its response time target.
Meaning: Notifies teams when performance requires attention.
5. Track Response Time Percentiles
Example: When checking how the slowest customer requests perform.
Meaning: Shows performance beyond a simple average.
6. Monitor Applications Around the Clock
Example: When supporting customers across multiple time zones.
Meaning: Helps detect problems outside normal working hours.
7. Check Service Availability Alongside Speed
Example: When verifying that a fast response also returns successfully.
Meaning: Combines responsiveness with basic service reliability.
8. Watch Resource Usage in Real Time
Example: When response times increase alongside high CPU usage.
Meaning: Helps connect performance changes with resource pressure.
9. Identify Repeated Slow Requests
Example: When the same API endpoint regularly exceeds its target.
Meaning: Makes recurring performance problems easier to investigate.
10. Correlate Alerts With Application Events
Example: When slow responses begin after a software deployment.
Meaning: Helps connect performance changes to recent system activity.
11. Monitor Dependencies Live
Example: When an application relies on external payment services.
Meaning: Reveals delays originating outside the main application.
12. Review Live Metrics During Incidents
Example: When investigating a sudden outage or severe slowdown.
Meaning: Supports faster troubleshooting with current evidence.
3. Professional Application Response Time Monitoring Practices
1. Define Service-Level Objectives
Example: When agreeing on performance goals for a business application.
Meaning: Establishes measurable expectations for service responsiveness.
2. Document Monitoring Standards
Example: When creating guidelines for an operations team.
Meaning: Ensures consistent monitoring across application environments.
3. Build Performance Reports
Example: When presenting application health to company leadership.
Meaning: Communicates important trends and operational risks.
4. Prioritize Business-Critical Services
Example: When monitoring payment processing before less important features.
Meaning: Directs attention toward services with the greatest business impact.
5. Establish Alert Escalation Rules
Example: When an unresolved performance issue requires additional support.
Meaning: Clarifies who should respond as an incident develops.
6. Maintain Performance Baselines
Example: When defining normal response times before a major release.
Meaning: Creates a reference point for detecting unusual behavior.
7. Review Service-Level Agreements
Example: When checking whether application performance meets contractual commitments.
Meaning: Connects monitoring targets with agreed service expectations.
8. Assign Monitoring Responsibilities
Example: When separating development and operations duties.
Meaning: Makes ownership of performance issues clear.
9. Maintain an Incident History
Example: When recording the cause of a recurring slowdown.
Meaning: Helps teams recognize patterns and prevent repeated incidents.
10. Audit Monitoring Coverage
Example: When checking whether important endpoints have performance alerts.
Meaning: Reveals gaps that could leave problems unnoticed.
11. Communicate Performance Risks Clearly
Example: When explaining a technical delay to nontechnical managers.
Meaning: Translates monitoring findings into understandable business implications.
12. Review Targets After Major Changes
Example: When application traffic doubles after a new product launch.
Meaning: Keeps performance expectations aligned with changing demands.
4. Application Response Time Monitoring Tools and Metrics
1. Use Application Performance Monitoring
Example: When tracking transactions across a complex web application.
Meaning: Connects response times with application behavior and potential bottlenecks.
2. Measure Average Latency
Example: When comparing overall responsiveness between two releases.
Meaning: Summarizes typical request duration but may hide slow outliers.
3. Track the 95th Percentile
Example: When evaluating whether most customers receive timely responses.
Meaning: Shows the response time below which 95% of measured requests fall.
4. Track the 99th Percentile
Example: When investigating unusually slow customer requests.
Meaning: Helps reveal performance problems affecting the slowest portion of requests.
5. Monitor Throughput
Example: When checking requests processed per second during a traffic surge.
Meaning: Shows how much work an application handles over time.
6. Measure Error Rates
Example: When response times increase alongside failed API requests.
Meaning: Helps distinguish slow successful requests from unsuccessful operations.
7. Monitor CPU Utilization
Example: When a server becomes slow under heavy computational workloads.
Meaning: Helps identify CPU pressure that may affect response times.
8. Track Memory Consumption
Example: When application latency rises during extended usage.
Meaning: Helps investigate memory pressure and related performance issues.
9. Inspect Database Query Duration
Example: When customer reports load slowly despite a responsive interface.
Meaning: Reveals whether database operations contribute to application delays.
10. Measure Network Latency
Example: When a remote service responds slowly across regions.
Meaning: Helps determine whether network communication contributes to delays.
11. Use Distributed Tracing
Example: When following a request through multiple backend services.
Meaning: Identifies where time is spent across a distributed transaction.
12. Compare Metrics in One Dashboard
Example: When investigating latency alongside errors and server resources.
Meaning: Makes relationships between performance indicators easier to spot.
5. Funny Application Response Time Monitoring Sayings
1. My Application Needs a Coffee Break
Example: When a dashboard takes forever to load during a demonstration.
Meaning: Jokes about an application responding more slowly than expected.
2. Response Time Has Entered Its Loading Era
Example: When an app displays a spinner longer than anyone expected.
Meaning: Playfully describes persistent loading delays.
3. Monitoring the Art of Doing Nothing
Example: When a request remains pending without useful progress.
Meaning: Highlights frustrating delays with a little humor.
4. Our Latency Is Writing a Novel
Example: When an API response takes far too long.
Meaning: Exaggerates a slow response for comic effect.
5. The Server Is Thinking Very Deeply
Example: When a simple page takes several seconds to appear.
Meaning: Makes light of an unexplained server delay.
6. Loading Faster Is Apparently a Premium Feature
Example: When a free application feels noticeably sluggish.
Meaning: Uses sarcasm to express frustration with poor responsiveness.
7. The Spinner Deserves Employee of the Month
Example: When a loading indicator appears on nearly every screen.
Meaning: Jokes about an interface that spends too much time loading.
8. Our Requests Took the Scenic Route
Example: When network calls are slower than expected.
Meaning: Humorously suggests requests are taking unnecessary detours.
9. Latency Is Having Its Main Character Moment
Example: When a performance spike dominates the monitoring dashboard.
Meaning: Playfully emphasizes an unusually prominent delay.
10. The App Is Buffering Its Life Choices
Example: When a page freezes just before an important presentation.
Meaning: Adds personality to an otherwise frustrating performance issue.
11. Our Response Times Need a Pep Talk
Example: When a release performs below the team’s expectations.
Meaning: Expresses the need for performance improvement humorously.
12. The Dashboard Is Practicing Patience on Everyone
Example: When reports load slowly during a team meeting.
Meaning: Turns a shared performance annoyance into a relatable joke.
6. Clever Application Response Time Monitoring Insights
1. Measure What Users Actually Feel
Example: When deciding which performance metric deserves attention first.
Meaning: Prioritizes meaningful user experience over vanity metrics.
2. Fast Averages Can Hide Slow Experiences
Example: When average latency looks good but customers still complain.
Meaning: Explains why percentile measurements are important.
3. Every Millisecond Tells a Story
Example: When comparing request timings across several application releases.
Meaning: Encourages careful investigation of performance changes.
4. Monitor the Journey, Not Just the Destination
Example: When tracking a transaction across multiple backend services.
Meaning: Focuses on the full request path rather than one endpoint.
5. Performance Problems Leave Patterns
Example: When delays appear every afternoon during peak traffic.
Meaning: Encourages teams to identify recurring causes instead of guessing.
6. A Fast Server Cannot Fix Every Slow Request
Example: When network delays or database queries dominate total latency.
Meaning: Reminds teams to investigate the entire application architecture.
7. Context Makes Metrics Useful
Example: When comparing response times before and after deployment.
Meaning: Shows why measurements need meaningful baselines and event history.
8. The Slowest Requests Often Teach the Most
Example: When investigating unusually high latency percentiles.
Meaning: Directs attention toward hidden bottlenecks.
9. Alerts Should Lead to Action
Example: When designing notifications for the operations team.
Meaning: Encourages actionable alerts rather than unnecessary noise.
10. Better Monitoring Means Fewer Surprises
Example: When preparing for a high-traffic product launch.
Meaning: Highlights the preventive value of performance visibility.
11. Speed Without Reliability Is Incomplete
Example: When a service responds quickly but returns errors.
Meaning: Emphasizes that good performance includes successful outcomes.
12. Small Delays Can Reveal Big Problems
Example: When latency gradually increases over several days.
Meaning: Encourages investigation before minor issues become serious incidents.
7. Sarcastic Application Response Time Monitoring Comments
1. Five Seconds for a Login? Very Efficient.
Example: When a routine sign-in process becomes painfully slow.
Meaning: Criticizes a response time that falls below expectations.
2. The Server Clearly Has Other Priorities
Example: When a request waits while the application appears unresponsive.
Meaning: Expresses frustration with delayed processing.
3. Real-Time Monitoring, Fictional Response Speeds
Example: When dashboards update quickly but the application does not.
Meaning: Highlights the difference between visibility and actual performance.
4. Our Latency Is Building Suspense
Example: When a customer waits for a page to finish loading.
Meaning: Uses irony to emphasize an unnecessarily long delay.
5. The Database Must Be on Vacation
Example: When database-heavy screens suddenly slow down.
Meaning: Jokes about a possible backend bottleneck.
6. That Loading Screen Has Job Security
Example: When a spinner appears on every major application screen.
Meaning: Mocks a persistent loading problem.
7. The API Responded Eventually, So There’s That
Example: When an API completes a request after a long wait.
Meaning: Offers a sarcastic take on barely acceptable responsiveness.
8. Our Performance Goals Are Feeling Ambitious Today
Example: When the latest monitoring report misses its targets.
Meaning: Lightly criticizes performance that fails to meet expectations.
9. Apparently, Instant Means Sometime Today
Example: When an application takes much longer than expected to respond.
Meaning: Exaggerates a slow experience for humorous effect.
10. The Timeout Is Doing All the Work
Example: When requests repeatedly exceed their allowed duration.
Meaning: Points out that requests are failing to complete promptly.
11. We Have Achieved Maximum Waiting Potential
Example: When a report remains stuck in a loading state.
Meaning: Expresses frustration through deliberate exaggeration.
12. Performance Testing Would Like a Word
Example: When a new release introduces obvious slowdowns.
Meaning: Suggests that stronger performance testing is needed.
8. Professional Responses for Application Performance Reports
1. Response Times Remain Within the Defined Target
Example: When reporting healthy performance during a routine review.
Meaning: Confirms that measured latency meets the agreed objective.
2. Elevated Latency Requires Further Investigation
Example: When monitoring identifies a persistent slowdown.
Meaning: Communicates a performance concern without assigning blame prematurely.
3. The Issue Is Under Active Investigation
Example: When a team is diagnosing a production performance incident.
Meaning: Provides a professional update while analysis continues.
4. Performance Metrics Are Being Reviewed
Example: When validating an unexpected dashboard result.
Meaning: Signals that the team is checking the available evidence.
5. The Current Baseline Indicates a Performance Deviation
Example: When latency increases compared with normal behavior.
Meaning: Identifies a measurable change from expected performance.
6. We Are Assessing the Impact on Critical Transactions
Example: When a slowdown affects important business workflows.
Meaning: Explains that the team is evaluating user and business impact.
7. Monitoring Coverage Is Being Expanded
Example: When adding instrumentation to an overlooked endpoint.
Meaning: Communicates an effort to improve performance visibility.
8. The Latest Release Requires Performance Validation
Example: When reviewing an application after deployment.
Meaning: Indicates that post-release testing is necessary.
9. Response Time Trends Will Be Evaluated Against Historical Data
Example: When preparing a monthly performance review.
Meaning: Explains how historical measurements will support the assessment.
10. An Alert Threshold Adjustment Is Under Review
Example: When a notification repeatedly fires without meaningful incidents.
Meaning: Indicates that alert sensitivity is being evaluated.
11. The Suspected Bottleneck Has Been Isolated
Example: When tracing identifies a slow database operation.
Meaning: Reports progress toward locating the cause of the delay.
12. Corrective Actions Will Be Verified Through Monitoring
Example: When confirming whether a performance fix worked.
Meaning: Emphasizes evidence-based validation after remediation.
9. Application Response Time Monitoring for Developers
1. Instrument Your Critical Code Paths
Example: When measuring the duration of important backend operations.
Meaning: Makes time-consuming code easier to identify.
2. Profile Before You Optimize
Example: When a page is slow but the cause remains unclear.
Meaning: Encourages evidence-based performance improvements.
3. Trace Requests Across Services
Example: When a request passes through several microservices.
Meaning: Helps developers locate delays across service boundaries.
4. Measure Database Calls Separately
Example: When investigating a slow API endpoint.
Meaning: Distinguishes database delays from other processing costs.
5. Inspect Synchronous Dependencies
Example: When an API waits for several external services.
Meaning: Reveals dependencies that may extend total response time.
6. Review Connection Pool Utilization
Example: When database requests queue during peak traffic.
Meaning: Helps uncover connection shortages that contribute to latency.
7. Check Cache Hit Rates
Example: When repeated requests remain unexpectedly slow.
Meaning: Helps determine whether caching is reducing unnecessary work.
8. Optimize Expensive Queries
Example: When a database query dominates transaction duration.
Meaning: Targets a potential source of backend latency.
9. Avoid Unnecessary Network Round Trips
Example: When an application makes repeated calls for related data.
Meaning: Reduces communication overhead where appropriate.
10. Test Under Realistic Workloads
Example: When preparing a service for a seasonal traffic increase.
Meaning: Reveals bottlenecks that may not appear in small tests.
11. Compare Performance Before and After Changes
Example: When evaluating a refactored endpoint.
Meaning: Verifies whether code changes actually improve responsiveness.
12. Add Regression Checks to Performance Testing
Example: When preventing a previously fixed slowdown from returning.
Meaning: Makes performance protection part of ongoing development.
10. Application Response Time Monitoring for Websites
1. Monitor Homepage Load Performance
Example: When checking the first page visitors encounter.
Meaning: Helps identify delays affecting initial impressions.
2. Track Core User Journeys
Example: When testing product search, cart updates, and checkout.
Meaning: Measures responsiveness throughout meaningful website interactions.
3. Measure Time to First Byte
Example: When investigating how quickly a browser receives its first response byte.
Meaning: Helps assess server response and network delivery delays.
4. Monitor Largest Contentful Paint
Example: When evaluating how quickly the main visible content appears.
Meaning: Measures an important aspect of perceived loading performance.
5. Check Interaction Responsiveness
Example: When users report that buttons feel slow after a page loads.
Meaning: Helps assess whether interactions respond promptly.
6. Compare Mobile and Desktop Performance
Example: When mobile visitors experience slower shopping pages.
Meaning: Reveals performance differences across device categories.
7. Monitor Third-Party Scripts
Example: When analytics or advertising scripts delay page rendering.
Meaning: Helps identify external code affecting website performance.
8. Review Image and Asset Delivery
Example: When large images delay a product page.
Meaning: Highlights opportunities to improve resource loading.
9. Test From Multiple Regions
Example: When international visitors report slower access.
Meaning: Reveals geographic differences in network and service performance.
10. Track Performance During Campaigns
Example: When a marketing promotion sends a sudden wave of traffic.
Meaning: Helps evaluate website responsiveness during demand spikes.
11. Compare Synthetic and Real-User Data
Example: When laboratory tests disagree with customer experiences.
Meaning: Combines controlled measurements with actual user observations.
12. Monitor Checkout Response Times
Example: When shoppers abandon purchases during payment processing.
Meaning: Helps identify delays in a high-value website workflow.
11. Application Response Time Monitoring for APIs
1. Track Latency by Endpoint
Example: When comparing search, authentication, and payment APIs.
Meaning: Identifies endpoints with different performance characteristics.
2. Monitor API Error Rates
Example: When requests begin returning server errors.
Meaning: Helps determine whether slowdowns coincide with failed requests.
3. Set Endpoint-Specific Thresholds
Example: When a search endpoint has different requirements from a reporting API.
Meaning: Aligns response time targets with individual service needs.
4. Measure Cold-Start Delays
Example: When a serverless function responds slowly after inactivity.
Meaning: Identifies initialization overhead affecting the first request.
5. Check Rate-Limiting Behavior
Example: When API responses change during heavy client traffic.
Meaning: Helps distinguish intentional throttling from other latency issues.
6. Inspect Authentication Overhead
Example: When token validation increases request duration.
Meaning: Reveals the time spent verifying access credentials.
7. Monitor External API Dependencies
Example: When a delivery service depends on a third-party tracking API.
Meaning: Helps identify latency originating in external systems.
8. Measure Payload Processing Time
Example: When large JSON responses take longer to process.
Meaning: Highlights serialization and payload-related overhead.
9. Track Queue Waiting Time
Example: When requests wait before reaching a worker.
Meaning: Identifies delays caused by overloaded processing queues.
10. Validate Timeout Settings
Example: When requests fail before the backend finishes processing.
Meaning: Helps ensure timeout limits match realistic service requirements.
11. Review API Performance by Version
Example: When comparing a new endpoint version with its predecessor.
Meaning: Reveals whether changes improve or degrade responsiveness.
12. Test APIs With Representative Traffic
Example: When simulating normal and peak request volumes.
Meaning: Evaluates latency under realistic usage conditions.
12. Creative Ways to Explain Response Time Monitoring
1. Think of It as a Digital Stopwatch
Example: When explaining monitoring to someone new to IT.
Meaning: Describes measuring the time between a request and its response.
2. Give Every Request a Travel Diary
Example: When tracing a transaction across backend services.
Meaning: Makes the request’s processing journey easier to understand.
3. Treat Latency Like a Queue at Checkout
Example: When several users compete for limited server resources.
Meaning: Illustrates how waiting and congestion increase response times.
4. Imagine a Traffic Report for Your Application
Example: When explaining a live performance dashboard.
Meaning: Describes how monitoring reveals congestion and delays.
5. Think of Alerts as a Digital Doorbell
Example: When explaining threshold-based notifications to a new teammate.
Meaning: Shows how alerts bring attention to conditions requiring action.
6. Give Your App a Performance Fitness Test
Example: When preparing an application for a major launch.
Meaning: Presents performance testing as preparation for demanding workloads.
7. Use a Speedometer for Every Endpoint
Example: When comparing latency across multiple API routes.
Meaning: Makes differences in response speed easy to visualize.
8. Treat Baselines Like a Normal Heartbeat
Example: When identifying unusual latency patterns.
Meaning: Uses a familiar comparison for understanding normal system behavior.
9. Turn Logs Into a Performance Story
Example: When investigating what happened during a slowdown.
Meaning: Shows how recorded events help explain application behavior.
10. Make Bottlenecks the Mystery to Solve
Example: When organizing a team troubleshooting session.
Meaning: Encourages systematic investigation instead of guesswork.
11. Imagine Percentiles as Different Waiting Experiences
Example: When explaining why some users wait longer than others.
Meaning: Makes latency distributions easier to understand.
12. Think of Optimization as Removing Roadblocks
Example: When improving a slow transaction workflow.
Meaning: Frames performance improvement as eliminating unnecessary delays.
13. Confident Responses to Application Performance Issues
1. We Have the Metrics to Find the Cause
Example: When beginning a structured performance investigation.
Meaning: Communicates confidence in the available diagnostic evidence.
2. The Next Step Is Clear
Example: When monitoring identifies a specific bottleneck.
Meaning: Shows readiness to move from analysis to action.
3. We Will Verify the Fix With Real Measurements
Example: When deploying a latency improvement.
Meaning: Emphasizes measurable results rather than assumptions.
4. Our Monitoring Covers the Critical User Journeys
Example: When explaining how important workflows are observed.
Meaning: Communicates that key application activities are being tracked.
5. We Are Comparing Results Against a Reliable Baseline
Example: When evaluating a performance regression.
Meaning: Shows that conclusions rely on meaningful comparisons.
6. The Team Is Prioritizing the Highest-Impact Bottleneck
Example: When several performance issues compete for attention.
Meaning: Communicates a practical, impact-focused approach.
7. We Can See Where the Time Is Going
Example: When distributed tracing identifies a slow dependency.
Meaning: Expresses confidence in the diagnostic findings.
8. Performance Will Be Validated Before Closure
Example: When an incident appears resolved.
Meaning: Confirms that the team will check the outcome before closing the issue.
9. We Are Measuring Improvement, Not Guessing
Example: When reviewing a proposed optimization.
Meaning: Reinforces evidence-based decision-making.
10. The Response Time Trend Is Moving in the Right Direction
Example: When latency decreases after a successful fix.
Meaning: Communicates measurable progress toward better performance.
11. We Have a Plan for Preventing Recurrence
Example: When documenting actions after a production incident.
Meaning: Shows commitment to long-term reliability.
12. Monitoring Will Keep Us Accountable
Example: When introducing new performance objectives.
Meaning: Emphasizes ongoing verification against established targets.
14. Chill and Casual Application Monitoring Updates
1. The App Is Looking Pretty Healthy Today
Example: When sharing a routine status update with teammates.
Meaning: Communicates that current performance looks normal.
2. Response Times Are Staying in Check
Example: When reviewing a stable monitoring dashboard.
Meaning: Indicates that latency remains within expected limits.
3. Nothing Major Is Slowing Things Down Right Now
Example: When reporting that no significant bottleneck has been detected.
Meaning: Offers a relaxed summary of current performance.
4. We’re Keeping an Eye on the Slow Spots
Example: When tracking a few endpoints that need attention.
Meaning: Communicates continued monitoring without unnecessary alarm.
5. The Latest Release Looks Smooth So Far
Example: When checking performance after a deployment.
Meaning: Shares a positive early assessment while leaving room for further validation.
6. The Dashboard Is Staying Quiet
Example: When no significant performance alerts are firing.
Meaning: Suggests that no major monitored issues are currently apparent.
7. We’re Checking the Usual Suspects
Example: When investigating familiar causes of application latency.
Meaning: Describes a routine troubleshooting process casually.
8. The API Is Keeping Up With Traffic
Example: When request volumes increase without a noticeable slowdown.
Meaning: Indicates that the service is handling current demand.
9. We’re Watching the Numbers Before Calling It Fixed
Example: When a recent performance issue appears to have improved.
Meaning: Communicates cautious optimism while validation continues.
10. The Slowdown Seems to Be Settling Down
Example: When latency begins returning toward normal levels.
Meaning: Describes an improving trend without claiming complete resolution.
11. The Metrics Look Better Than Yesterday
Example: When comparing current latency with the previous day’s results.
Meaning: Shares a simple observation about improved performance.
12. We’ll Keep Monitoring and See How It Goes
Example: When a temporary issue has not fully disappeared.
Meaning: Communicates a measured approach to continued observation.
15. Sweet and Encouraging Application Monitoring Messages
1. Every Little Improvement Counts
Example: When celebrating a small reduction in response time.
Meaning: Recognizes incremental progress toward better performance.
2. Here’s to Faster Clicks and Happier Users
Example: When sharing a successful optimization with the team.
Meaning: Connects technical improvements with a better user experience.
3. Our Hard Work Is Showing in the Metrics
Example: When monitoring confirms that recent changes helped.
Meaning: Celebrates evidence of the team’s efforts.
4. A Smoother Experience Starts With Better Visibility
Example: When introducing monitoring to a development team.
Meaning: Highlights the value of understanding application behavior.
5. Small Fixes Can Make a Big Difference
Example: When a minor code change improves an important workflow.
Meaning: Encourages practical improvements rather than unnecessary complexity.
6. Let’s Make Waiting Less of a Thing
Example: When setting goals for a website optimization sprint.
Meaning: Encourages the team to reduce unnecessary delays.
7. Every Request Deserves a Timely Response
Example: When reviewing service quality expectations.
Meaning: Reinforces a commitment to responsive applications.
8. Better Data Makes Better Decisions
Example: When using monitoring results to prioritize development work.
Meaning: Emphasizes informed decisions over guesswork.
9. Progress Looks Good on Our Dashboard
Example: When latency trends improve after optimization.
Meaning: Celebrates measurable progress in application responsiveness.
10. We’re Building an Experience Worth Coming Back To
Example: When improving the speed of a customer-facing platform.
Meaning: Connects technical quality with customer satisfaction.
11. Keep Improving, Keep Measuring
Example: When establishing an ongoing performance review routine.
Meaning: Encourages continuous optimization and verification.
12. Fast, Reliable, and Ready for What’s Next
Example: When preparing an application for future growth.
Meaning: Expresses confidence in a focus on performance and reliability.
FAQs
What Does Application Response Time Monitoring Mean?
Application response time monitoring measures how long applications take to respond to user requests.
What Is a Good Application Response Time?
It depends on the task, but many interactive actions benefit from responses within a few hundred milliseconds.
How Does Application Response Time Monitoring Work?
It collects timing data from requests, services, databases, and users to identify slowdowns and performance trends.
Which Metrics Matter Most for Application Monitoring?
Response time percentiles, average latency, throughput, error rates, and availability are useful starting points.
What Is the Difference Between Latency and Response Time?
Latency often describes delay in communication or processing, while response time measures the duration of a complete operation.
Which Tools Are Used for Application Response Time Monitoring?
Teams use application performance monitoring platforms, tracing systems, synthetic tests, and real-user monitoring solutions.
Why Is Application Response Time Monitoring Important for Businesses?
It helps teams find bottlenecks, improve customer experiences, and reduce the risk of performance-related business losses.
Can Response Time Monitoring Detect API Problems?
Yes. It can reveal slow endpoints, delayed dependencies, request queues, and performance regressions.
Is Real-Time Monitoring Better Than Periodic Monitoring?
Real-time monitoring helps detect urgent issues quickly, while periodic reviews reveal longer-term trends.
How Can I Improve Application Response Times?
Profile slow operations, optimize database queries, reduce unnecessary network calls, and validate changes through testing.
Is Humor Appropriate in Performance Reports?
Light humor works in informal team updates, but formal incident reports should prioritize clarity and professionalism.
What Should I Say When an Application Is Running Slowly?
Use a clear update such as, “We’re investigating elevated response times and will verify performance after the fix.”
Conclusion
Application response time monitoring isn’t just about collecting numbers or staring at dashboards until your coffee gets cold. It’s about understanding how applications behave, identifying problems early, and making every user interaction feel smoother. Whether you’re a developer tracking API latency, an IT professional managing production systems, or a business owner protecting customer satisfaction, the right monitoring habits make a real difference.
Start with meaningful metrics, establish realistic performance targets, and pay attention to the slowest requests instead of relying on averages alone. Use the tips and messages in this guide to improve your reporting, communicate issues clearly, and build better monitoring routines.